miércoles, 15 de julio de 2026

La IA no ha acabado con la ingeniería del software. La ha vuelto más importante.

Repositorio: https://github.com/davsuapas/spec-agent

Durante años hemos discutido qué metodología es mejor: la ingeniería tradicional o las metodologías ágiles.

Las metodologías tradicionales priorizan una planificación exhaustiva y una ingeniería de requisitos sólida antes de empezar a desarrollar. Las metodologías ágiles, por el contrario, apuestan por la adaptación continua, las iteraciones cortas y la entrega rápida de valor.

La realidad es que ninguna de las dos es mejor por sí sola. Todo depende del nivel de incertidumbre del proyecto.

El problema aparece cuando llevamos la agilidad al extremo.

En muchos equipos hemos confundido ser ágiles con dejar de documentar. La presión por entregar software rápidamente hace que muchas decisiones funcionales y arquitectónicas nunca queden registradas. Al principio no parece un problema, pero cuando el proyecto crece, cambia de manos o evoluciona durante años, empiezan a aparecer contradicciones, deuda técnica y una pérdida de conocimiento que puede llegar a comprometer el proyecto.

Todos hemos escuchado alguna vez la pregunta:

"¿Por qué se hizo así?"

Y la respuesta suele ser el silencio.

Creo que la llegada de los agentes de IA cambia por completo este escenario.

Por primera vez podemos recuperar una de las mejores prácticas de la ingeniería tradicional —las especificaciones— sin renunciar a la velocidad y flexibilidad de las metodologías ágiles.

Las especificaciones ya no tienen por qué ser documentos estáticos que nadie vuelve a leer. Pueden convertirse en artefactos vivos que evolucionan junto con el software.

Los agentes pueden ayudarnos a transformar ideas ambiguas en especificaciones claras, detectar inconsistencias, validar requisitos, mantener la coherencia entre decisiones y preservar el conocimiento del proyecto durante todo su ciclo de vida.

Para mí, esa es una de las mayores aportaciones de la IA al desarrollo de software. No escribir código, sino ayudarnos a pensar mejor antes de escribirlo.

Sin embargo, también creo que estamos cometiendo un error importante.

Cada vez veo más organizaciones intentando que perfiles exclusivamente de negocio, sin experiencia en ingeniería del software, desarrollen aplicaciones completas con IA con el objetivo de reducir costes. El problema no es la IA. El problema es pensar que la ingeniería deja de ser necesaria.

Las consecuencias aparecen cuando el software llega a producción.

"La IA lo preparó para Azure y nuestro despliegue era on-premise."

O cuando nadie es capaz de explicar por qué se tomaron determinadas decisiones arquitectónicas.

La IA puede generar código extraordinariamente rápido, pero sigue necesitando contexto, criterio y supervisión. Poner una herramienta tan potente en manos de quien no entiende los principios de la ingeniería del software es asumir riesgos que, tarde o temprano, terminan pagando los proyectos.

Los ingenieros no desaparecen al contrario, la IA convierte a un buen ingeniero en un profesional todavía más capaz.

Con esa idea en mente he desarrollado, de forma modesta, Spec-Agent, un proyecto open source inspirado en Spec Kit, pero con un enfoque diferente.

Mi objetivo no era sustituir las metodologías ágiles, sino incorporar dentro de ellas algunas de las fortalezas de la ingeniería tradicional: especificaciones, trazabilidad y memoria de las decisiones.

La plataforma está formada por un conjunto de agentes especializados (@spec/def, @spec/plan, @spec/tasks y @spec/valid) que acompañan al desarrollador durante todo el flujo de trabajo.

No toman las decisiones por nosotros, nos ayudan a tomarlas mejor.

Además, incorpora una memoria semántica basada en reglas de decisión que permite conservar el conocimiento arquitectónico del proyecto para que tanto personas como agentes puedan reutilizarlo en el futuro, evitando repetir errores y manteniendo la coherencia incluso cuando el proyecto evoluciona durante años.

En mi opinión, el futuro del desarrollo de software no pasa por elegir entre metodologías tradicionales, metodologías ágiles o inteligencia artificial.

Pasa por combinar lo mejor de las tres.

Si alguien quiere conocer el proyecto, aquí está el repositorio:

👉 https://github.com/davsuapas/spec-agent

lunes, 10 de junio de 2024

SWPC - Swimming pool controller


The project consists of monitoring the metrics of a swimming pool in real time using golang. The metrics are collected through sensors inside the pool connected to an esp32 board.

The board, depending on the parameters configured in the application via web, sends the metrics information to a server, which broadcasts the metrics to all the connected subscribers.

The metrics obtained by the user are: Temperature, ORP (Oxidation Reduction Potential) and PH. Other metrics such as chlorine and water quality are calculated by two predictive models (artificial intelligence), namely a regression model and a decision tree model.

The metrics can be visualised anytime and anywhere via a web application.

The system is prepared for both microcontroller and server crashes. Therefore, when one of the parts detects that the other is available, the system starts to work normally.


Special care has been taken regarding memory and cpu consumption. Specifically, measurements have been made and for 70 clients connected in real time, values of 20 MB of memory and 0.5% of cpu have been obtained. The system is ready to deploy in aws beanstalk immediately.


martes, 5 de mayo de 2020

Reactive programming

Reactive programming is emerging as a clear alternative to traditional architectures. According to the manifesto, these changes are happening because application requirements have changed dramatically in recent years. Only a few years ago a large application had tens of servers, seconds of response time, hours of offline maintenance and gigabytes of data. Today applications are deployed on everything from mobile devices to cloud-based clusters running thousands of multi-core processors. We need architectures that know how to take advantage of the performance of the cores in an efficient way. Systems built as Reactive Systems are more flexible, loosely-coupled and scalable

According to the manifesto the main advantages are

Responsive: The system responds in a timely manner if at all possible.
Resilient: The system stays responsive in the face of failure.  
Elastic: The system stays responsive under varying workload.
Message Driven: Reactive Systems rely on asynchronous message-passing to establish a boundary between components that ensures loose coupling, isolation and location transparency

One of the platforms that is betting on this type of architecture is Spring Framework. Bit by bit Spring is incorporating this architecture in all its projects, but sometimes it is not easy to implement because it is an incipient technology. 

To make it easier to learn, I leave you a link to a personal project, where it is made entirely with reactive programming and that can be helpful to learn their techniques when approaching a project of this kind. The project is divided into the following sections:

  •  carisa-core: A framework of support. In this framework there are different classes to handle aggregate in Nosql databases.


I hope it helps you...

jueves, 5 de diciembre de 2019

How to load platforms in Spring Cloud Skipper using REST service

Skipper is a lightweight tool that lets you discover Spring Boot applications and manage their lifecycle on multiple Cloud Platforms. You can use Skipper standalone or integrate it with Continuous Integration pipelines to help implement the practice of Continuous Deployment.

Skipper consists of a server application that exposes an HTTP API. The problem is when you want configure the pltaform on fly. You can only configure the platform throught config files restarting spring cloud skipper service. Imagine that you wish create dinamically a platform using Skipper REST services no restarting services. To do this you can look at this extension.

The extension just allows load kubernetes platform, but it would be very easy do it to other platforms like cloud foundry.

The extension also stores the platforms into database. In this way you wont loose the platform information when restarting service.

By default, the unique information that is sended  in the request is the name and namespace. You could add more information to include in KubernetesDeployerProperties

POST /api/platforms/kubernetes/deployers

Thanks,

miércoles, 23 de enero de 2019

The power of Spring Cloud Pipeline and Spring Cloud Contract to deploy microservices on kubernetes

In this video we will try to describe how to deploy microservice architectures on kuberentes combining Spring Cloud Pipeline and Srping Cloud Contract. We will see how we can save time and money building our pipeline with Spring Cloud Pipeline and our tests using Spring Cloud Contract.


References in the video:

https://github.com/CloudPipelines/
https://spring.io/projects/spring-cloud-contract
https://github.com/davsuapas/DanceSchool
https://github.com/davsuapas/DanceSchool-CloudPipeline

miércoles, 26 de septiembre de 2018

Microservices security with Spring Cloud and how to integrate oauth2 with spring security roles

There is many ways to secure our microservices application depending of architecture. In this case we will have one front-end service and four back-end services behind of a proxy. We also will use oauth2 that allow to obtain limited access to an HTTP service, either on behalf of a resource owner by orchestrating an approval interaction between the resource owner and the HTTP service.


The interesting thing about oauth2 is that allows access to the resources of services using a security token. This token (JWT) contain all information necessary for working with the services. The token allow refresh when has expired. Using JWT we have the advantage that the resource server don't need checking the authorization with the ouath2 authorization server, because this information is found into token.

OAuth2 defines severals roles that we will see latter how to implement it with spring cloud

  • Resource Server: Services hosting protected data. Backend services.
  • Client: application requesting access to a resource server. Web 
  • Authorization Server: server issuing access token to the client. This token will be used for the client to request the resource server.
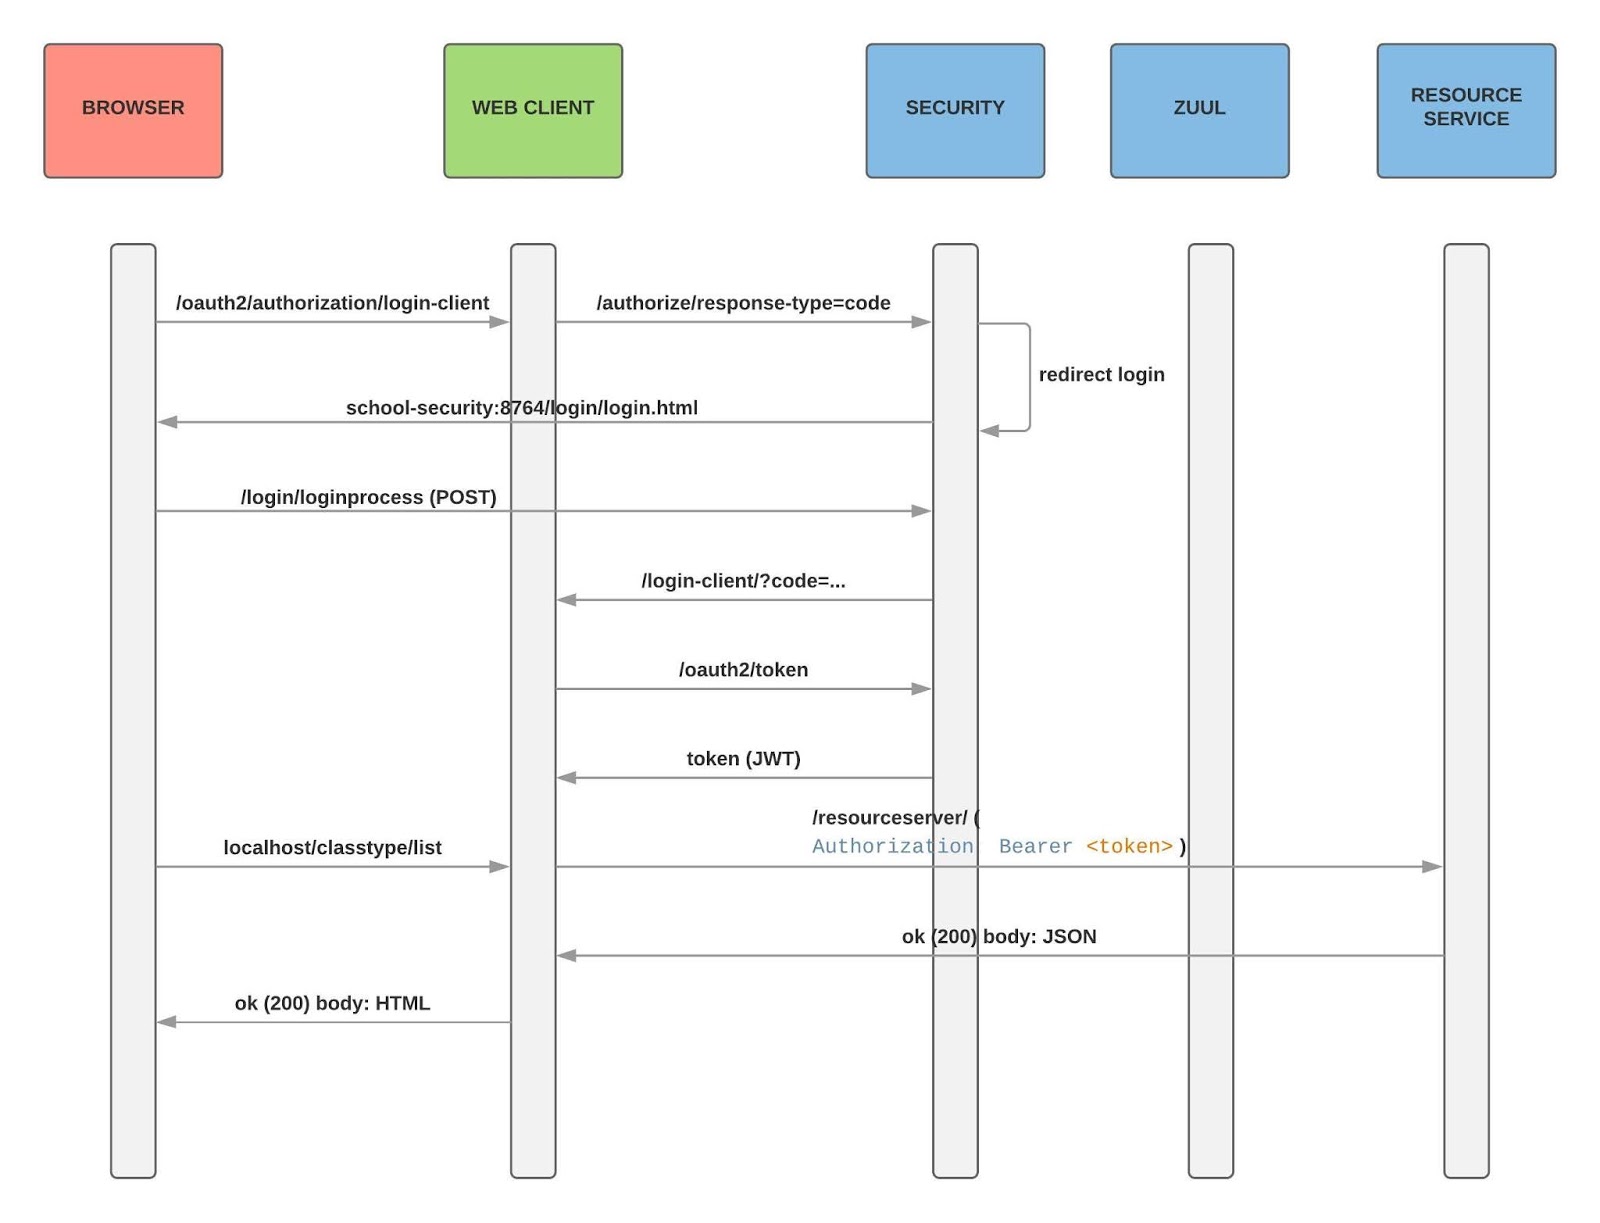
We will use authorization code grant to allow to the web layer to obtain a long-lived access token since it can be renewed with a refresh token. This token will be propagated throught ZuulProxy to the all backend services. We will see how configure ZuulProxy to allow authorization header.

Another aspect important is how to integrate oauth2 with spring security roles, since in a spring application it is easier use  spring security roles. We will see latter.

The authorization dance can be seen in the figure below:


Implementation


Authorization service

The authorization service is composed of two parts:

Oauth2 authorization server configuration. In this section we configure the ouath2 features as  the authorize grant type (authorization code) and the token type (jwt).


Web security configuration. Oauth2 has severals endpoint for authorization (/oauth/authorize) and for access token. This endpoint must be protected. To do this, we going to use web spring security. When a client tries access to /oauth/authorize endpoint, srping redirect the request to login page. 


Is important configure security.oauth2.resource.filter-order=5 to prioritize web security configuration over oauth2 configuration.

Client service (web)

We will use  spring oauth client. With Spring Security 5 is support for writing applications that integrate with services that are secured with OAuth 2. This includes the ability to sign into an application by way of an external service such as Facebook or GitHub or in our case with our own authorization service.

With Spring Security 5 is very easy configure the client service. The first step will be configure the autorization server as we can see in the figure below. In our case we configure a customer provider call school-provider.  The most important is define the security endpoints (authorization-url, toke-uri, etc). This endpoints are created  by spring oauth2 security.


When we request a token to the authorization service into this token comes the spring roles information. The problem is that spring oauth client doesen't inject this information (roles) into security context. We have that inject the roles into security context as we can see in the figure below.


From any service we need inject the authorization header with the barer token to communicate with others services, in our case using feign. Hence we must create a request interceptor and add the token in the requesttemplate, as we can see in the figure below.


The last step we need tell to spring all of the above in the configuration file.


In this point we already can use all features for securizing our web application.


Proxy service (zuul)

If we use a proxy service we must configure the proxy Zuul send all headers. To do this, we can define ignoreSecurityHeaders = true


Resource service (ClassroomSchool, etc)

The configuration is direct. It's configure of similar way that any application configurated with spring security. Adding @EnableResouceServer and we configure security roles for each endpoint. As we are using jwt token the spring oauth2 doesn't need connect with the authorization server to autorize the resource and get the security roles, because the information is into jwt token.


View code: Here

miércoles, 22 de noviembre de 2017

Spring Data Rest: Many to Many relations with extra atrributes


In many articles can see that if we want work many to many relations with extra colmuns the post/put requests must is done from  Classroom or ClassType entities in several steps. Example:

curl -i -X POST -H "Content-Type:application/json"
  -d "{\"name\":\"Room 1\"}" http://localhost:8080/Classrooms

curl -i -X POST -H "Content-Type:application/json"
  -d "{\"name\":\"Aerobic\"}" http://localhost:8080/ClassTypes

curl -i -X PUT -H "Content-Type:text/uri-list"
  --data-binary @uris.txt http://localhost:8080/Classrooms/1/ClassTypes

The uris.txt file contains the URIs of the ClassTypes, each on a separate line:
http://localhost:8080/ClassTypes/1

The problem is when i need do this in one transaction. To do this I need change focus and use as repository the Classroom/ClassType entity. In this case i could do this curl request:

curl -i -X POST -H "Content-Type:application/json" -d '{"id":{"classroom":"1","classType":"1"}, "classMax": 80}' http://localhost:8762/classroomproxy/classroomClassTypes/1_1

The JPA entity definition:

Classroom/ClassType


The repository


As the relation Classroom/ClassType (N to M) doesn't allow null, both for Classroom and for ClassType must load the information before saving in the database. If that is not done hibernate will generate an error saying "null reference". With Spring Data Rest we can handle the  creation events. Before creating we can get the class information of entities relations and then set ClassroomClassType


Id Converter

To allow the customization of how entity ids are exposed in URIs generated.


Configuration


viernes, 4 de agosto de 2017

Overriding Spring Data REST Response Handlers to share news methods in all repositories

With my obsession for reusing all developments. I decided include all features from my module Spring Data Extension into Spring Data Rest Extension.  Hence, I can use all my extensions of spring data across rest in any proyect, without having to create mapping request in each one of the projects. In this line, I avoid repeat code and avoid have to do unit test by each repository that i make.

To explain how i have extended the spring data rest, i use like sample, the updating embedded documents that i made in spring data extension.

The more important is creates my own rest repository controller.

This class must have marked @RepositoryRestController annotation.


As we can see in the figure above, the mapping url is the union between BASE_MAPPING and "{id}/mergeembedded/{embeddedProperty}".


  • BASE_MAPPING: Contain the base path and repository name.
  • {id}: Identifier of the repository. In this point isn't used, but we'll see that the id is handled by PersistentEntityResourceHandlerMethodArgumentResolver.
  • {embeddedProperty}: Property name of the domain to get embedded information.


Another important thing in this class is get a invoker to execute, (in this case), the merge function. We get the invoker object using resourceInformation.getInvoker(). RootResourceInformation is the class that serves as bridge between repository rest controller and repository.

The next step is connect our repository invoker with RootResourceInformation. This connection is done by the class that resolves the arguments of the request.


The spring guys have provided us a method called postProcess where we can do this.

Spring Data Rest when processes the patch method does a merge between request content, (repository domain), and the persistent repository . This domain is sended to controller and is recoveried across getContext(). In my case, this operation don't want do it, because the merge embedded function already does this operation. I wan't get the original request domain in my custom controller. To change this behaviour, we have override PersistentEntityResourceHandlerMethodArgumentResolver.


Depending of a request header property and patch method is applied the update no merge feature or the default function.

The next step consists in says to spring data rest configuration that it uses the new funcionality. Hence, we override RepositoryRestMvcConfiguration. This class configure all necesary for spring data rest.


Finally, we going to create a configuration interface to do more easy the configuration to the developer.


How can we use this news features in our project?. We going to see a sample.

Steps:


  1. Define domains. Look at MongoDomain and MongoEmbeddedDomain.
  2. Define repository. Look at MongoRepository.
  3. Define @EnabledRepositoryExtensionRestMvc. Look at RestWebMvcConfiguration

Once defined all necesary in my project, we can use the news rest services methods across the curl utility or whatever. Look sample at integration test.


Full Sorce code.


martes, 28 de marzo de 2017

Custom adapters and runtime dynamic configuration with spring integration

Six month ago, We had develop a prototype to integrate differents ERP (enterprise resource planning) information across ftp system. One of the ERP used a rest endpoint to receive information. But the other ERP, could only use the ftp system to communicate information. it could not send information using rest endpoint.

Other issue of the project is that the client would want have the full control to configure ftp options. We had build a system where the client might configure the ftp options using a portal web. We had build a listener to detect the changes in the database configuration and create dynamicly the ftp adapters

We used spring integration to develop the system. The problem is that spring integration is not very prepared to create adapter in runtime and had not inbound jdbc adapters watcher.

How did we resolve that problems?. 

  • We build custom inbound jdbc adapters watcher. JdbcInMemoryChangeWatcherAdapter. The adapter  detects changes of a table and sending the change information to the next channel. The updating is detected using a stamp field (watchField). This adapter only accept primary key of string type. The adapter works comparing all physic table information with a memory table, therefore this adapter is only prepared for small tables (normally configuration tables). 
  • Once that the system receives the changes, we load inbound ftp configuration from xml file configuration. Look at DynamicFtpWatcher . The ftp dynamic options is loaded using environment properties. The only problem that we found is that the bean ids can't be populated using environment variables, and we needed identifier every ftp configuration with diferrents ids. To resolve this problem, we created  PreProcessorXmlApplicationContext. This class preprocess xml configuration, replacing bean ids, before of generating GenericXmlApplicationContext. We might have load the application context using diferrents context, In this way, we would have had conflict problems, but we wanted load the ftp context into the same parent to reuse channel, transforms, etc.

In the under figure, we can see the flow of the spring integration application


1) Configuration database watcher (IntegrationConfiguration)


2) Ftp dynamic configuration watcher (FtpDynamic.xml)


Is neccesary save configuration id into header enricher, so that after the system know how to route  the rest message, (shared by all configurations) to the correct channel.

3) Send ftp file to rest endpoint (IntegrationConfiguration)


4) Remove resources (FtpDynamic.xml)


Remove ftp file and sync folder file.

The channel is only executed if  the response of the rest service is "OK" and the id is equal to original configuration. Remind the rest channel is shared by all configurations

expression="headers.ftpId.equals('${id}') and headers.http_statusCode == T(org.springframework.http.HttpStatus).OK">

5) End (IntegrationConfiguration)


Source code prototype: https://github.com/davsuapas/SpringIntegrationDynamic